
- FLUX.1 Kontext dev changes a photo according to a text instruction and leaves the rest of the frame alone.
- On a 32 GB Mac mini it runs in ComfyUI in Q8 if the text encoder and the model work in turn.
- Outputs may be used commercially, but the model has a non-commercial licence: I explain what that means.
In the second part of the series I test a model that does not create images from scratch, but fixes existing photos. FLUX.1 Kontext dev gets a photo and an instruction, for example “remove the hand with the microphone, replace the lamp with a turquoise triangle”, and changes only what you ask for. In my reel studio it prepared the start frame for a talking avatar. I check how long that takes on a Mac mini M6 with 32 GB, how much memory it uses and what the before and after look like.
What I need frame editing for in a reel studio
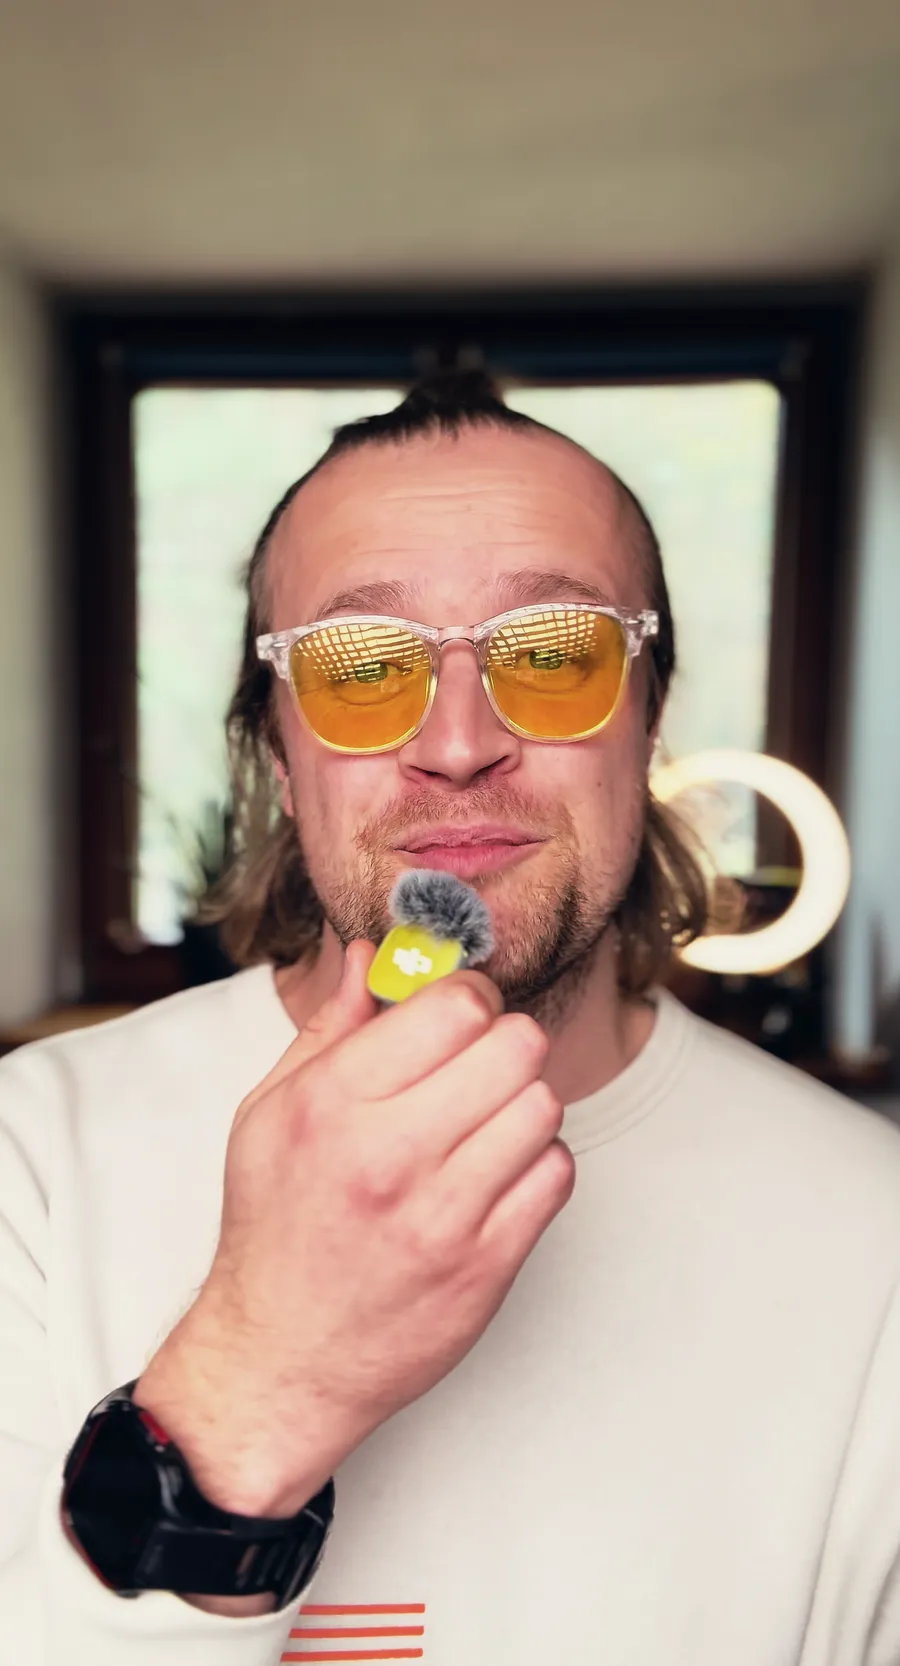
The AI avatar in my reel is made from one start frame and a voice recording. The video model animates that frame: it moves the lips, the head and the facial expressions. Everything on the start frame stays in the whole film. In my recording I was holding a fluffy microphone, and a round ring light, a ring-shaped lamp, was shining on the right. The microphone covered my chin just below the mouth, exactly the area the avatar has to animate. The ring light did not fit my brand.
Instead of recording everything again, I fix one frame. The instruction from the project is in English and tells the model three things:
- remove the hand holding the microphone, and let the arms hang relaxed below the frame,
- replace the ring light with a glowing turquoise triangle-shaped lamp, in the same place and of the same size,
- keep the face, the orange sunglasses, hair, beard, sweatshirt, window, room and lighting exactly the same.
It is a good test, because it combines removing an object, adding a new one and keeping the face, which viewers look at most closely.
The model and how it runs on a Mac
FLUX.1 Kontext dev is Black Forest Labs’ model for editing images with a text instruction. It is a diffusion model with 12B parameters: it starts from noise and step by step arrives at an image that matches the instruction and the input photo.
The full version of the model is too big to work with comfortably in 32 GB of memory. That is why I use a version after Q8 quantization, stored in the GGUF format. I run it in ComfyUI with the ComfyUI-GGUF add-on, which can load such files.
Two text encoders turn the text instruction into numbers: T5 (also in Q8) and CLIP-L. ComfyUI runs without a window, as a server, and calculates on the Mac’s graphics chip through PyTorch MPS.
| File | Size | |
|---|---|---|
| Image model | flux1-kontext-dev-Q8_0.gguf | 12.7 GB |
| Text encoder | t5-v1_1-xxl-encoder-Q8_0.gguf | 5.06 GB |
| Second encoder | clip_l.safetensors | 246 MB |
| Image decoder (VAE) | ae.safetensors | 335 MB |
The most important lesson from the project is about memory: the text encoder and the image model should not be in memory at the same time. That is why the studio encodes the instruction once, saves the result to disk and starts the ComfyUI server again before the actual edit. The server starts with the --cache-none option, which means it keeps no models in memory between jobs, so each job starts with empty memory. Models have to be loaded again every time, but the system does not need to use swap on disk.
What I measure and how
| Mac mini M6 (Mac18,5) | |
|---|---|
| Processor | Apple M6, 12 CPU cores: 2 Super, 4 Performance, 6 Efficiency |
| Graphics | 12 GPU cores, Metal 4 |
| Memory | 32 GB shared by the processor and graphics, 170 GB/s bandwidth |
| Storage | 512 GB SSD (494 GB formatted) |
| System | macOS 27.0.1 |
The input is a frame from one of my recordings (called v11 in the project). A script picked it automatically: it is sharp, the mouth is closed and the face looks straight into the camera. The model files sit on an external SSD connected over USB.
I run the edit with the same settings as in the project: 24 steps, guidance 2.5, the euler sampling method and three different random seed values (1, 2 and 3). I measure:
- the time of each edit (the first also includes encoding the instruction and starting the server again),
- the smallest amount of free memory during the work,
- the largest size of swap.
I take the measurement on a Mac with no other heavy programs running. I recorded a separate single run in a real Terminal window.

Results: before and after
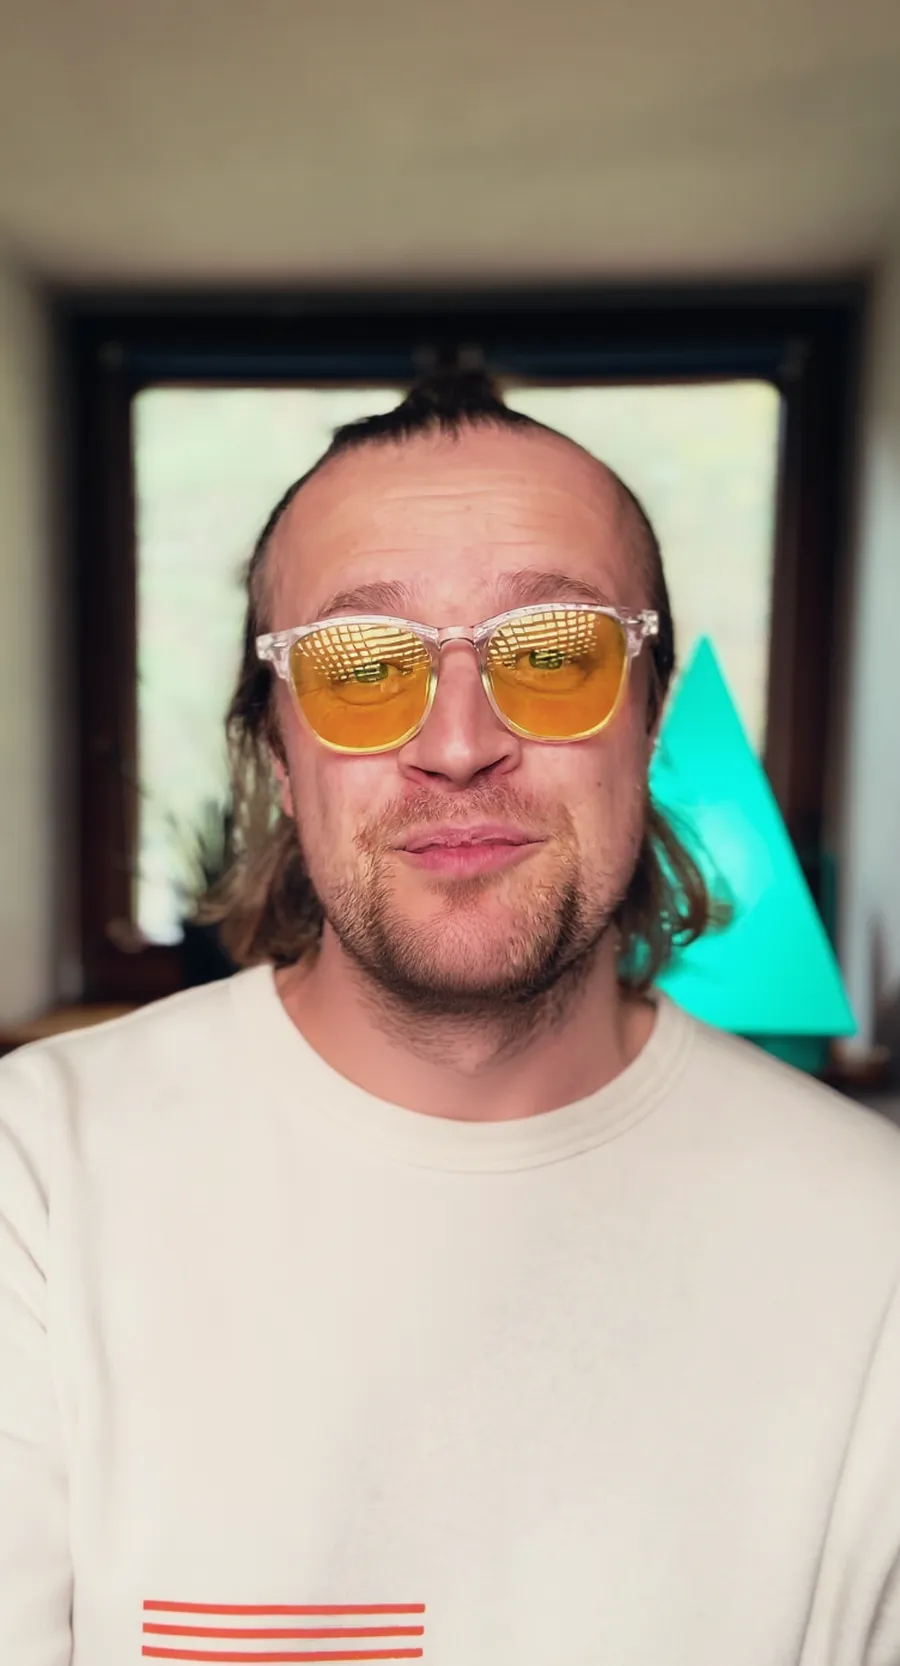
The main parts of the instruction worked in all three variants:
- the hand with the microphone disappeared, and in its place the model drew a smooth sweatshirt front with a round neckline, without any trace of fingers,
- the round ring light turned into a turquoise triangle-shaped lamp,
- the face, the orange sunglasses with the window reflection, the shape of the hair, the beard and the window stayed without visible changes, and the light in the room comes from the same side.
The model also did two things I did not ask for. It drew a part of the sweatshirt stripes that the forearm had covered before (a different length in each variant). It also added a turquoise glow from the new lamp on my hair, although the instruction asked for unchanged lighting.
The output is 752 pixels wide, so on the slider it looks softer than the 4K original. That comes from the lower resolution, not from a change to the face.
The model took the most freedom with the lamp. In variant 2, which I chose for the slider, the lamp stands behind my shoulder and partly hides behind my hair. In variant 1 it glows brighter and has a bright spot in the middle. In variant 3 it stands on a thin leg and fits fully in the frame. No variant stands exactly in the same place or has the same size as the ring light, although the instruction asked for that. The model understood what change I wanted, but did not copy the position and size. All triangles are clearly larger than the ring light (1.3–1.8 times taller) and all of them reach the height of the glasses, in variant 1 even higher, while the ring light started at nose height.
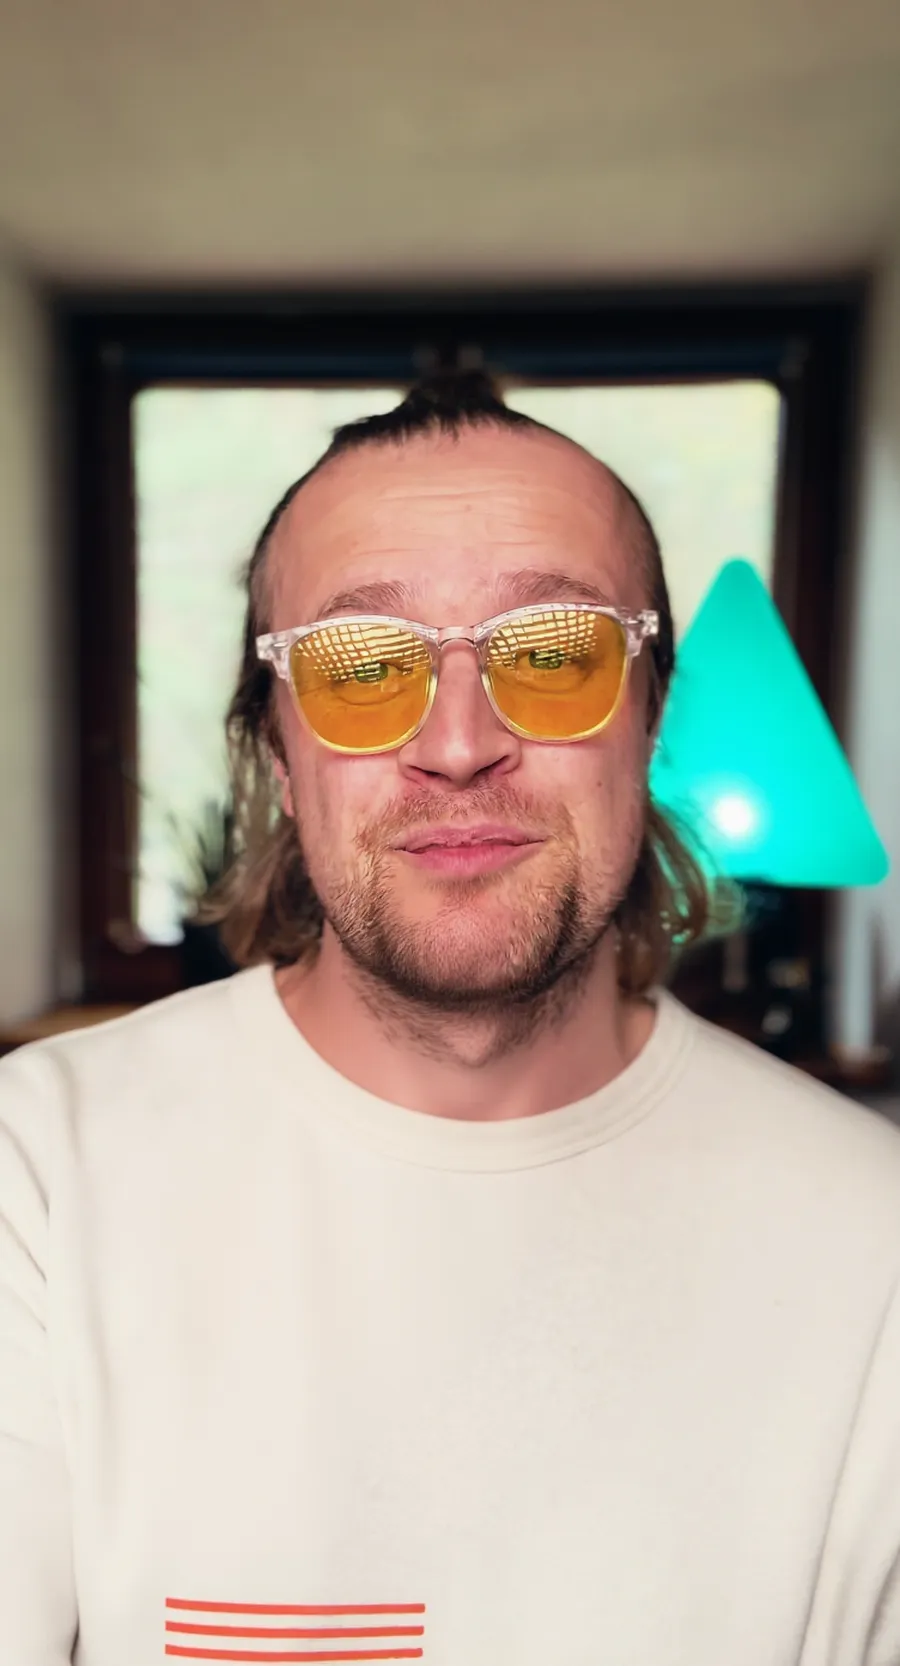 seed 1
- seed 2
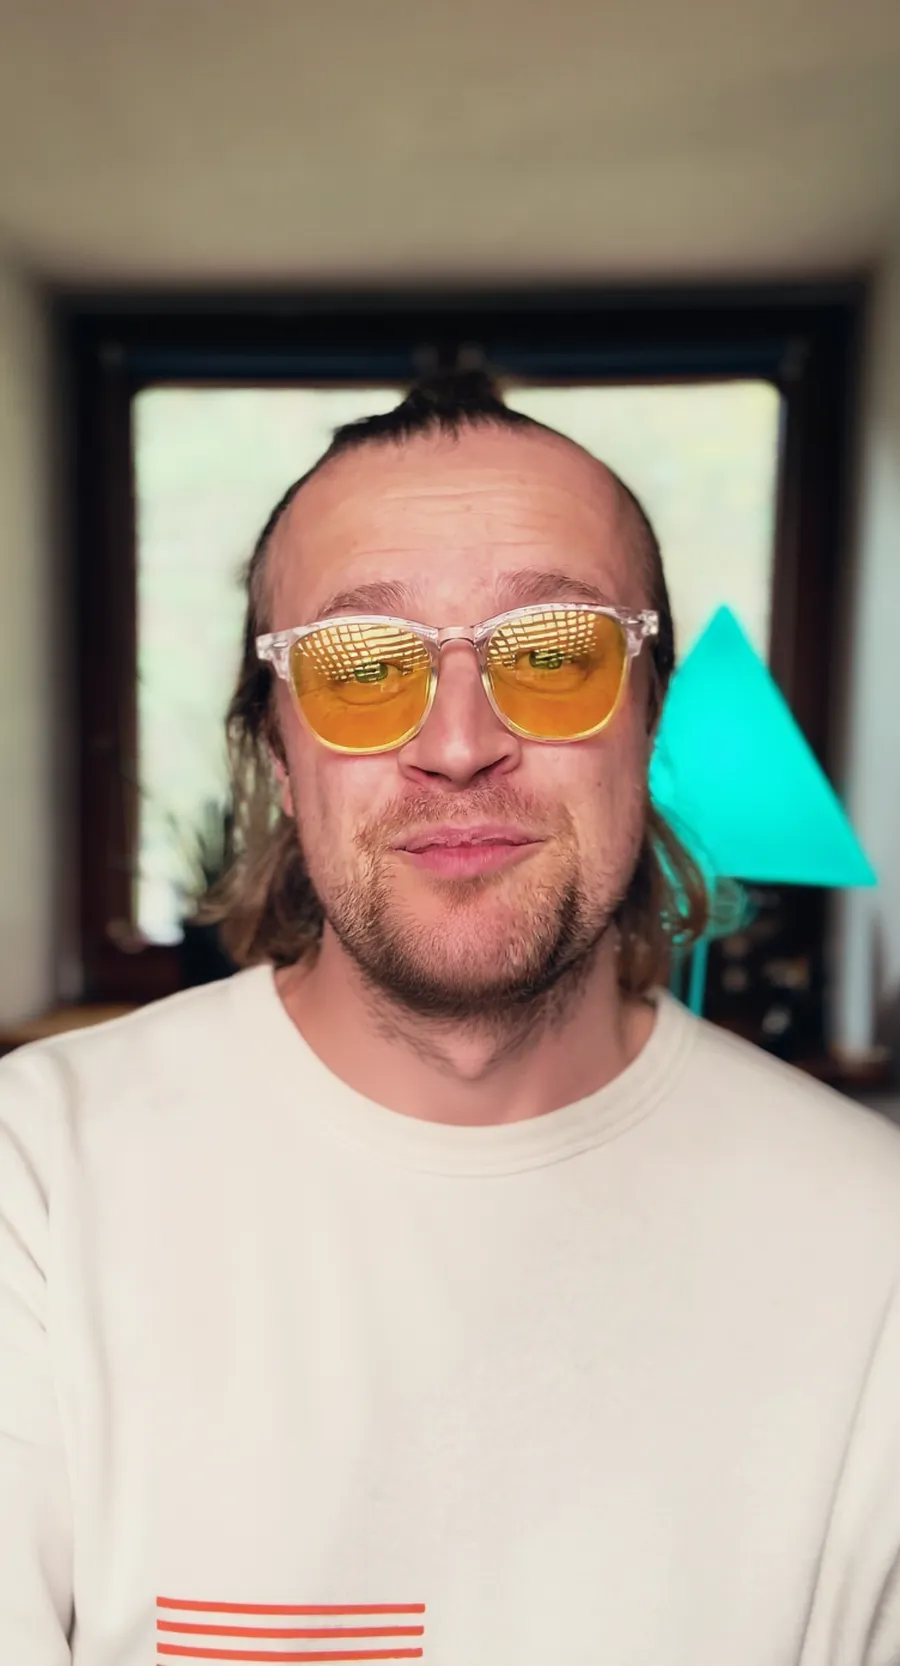 seed 3
Results: time and memory
One frame edit takes about 5.5 minutes on this Mac. The first took about 37 s longer, because it includes encoding the instruction with the T5 and CLIP encoders and starting the server again, which frees the memory used by the encoder. The rest of the time goes to the 24 steps of the model in its Q8 version.
Memory was tight, but enough. Before the test the system had 26.6 GB of free memory, and 6.0 GB at the worst moment. Swap did not grow above its level before the test, because the encoder and the model were never in memory at the same time.
So the edit took about 20.6 GB of the 32 GB, more than the model file alone. Besides the model, memory goes to the calculations on a 752 × 1392 pixel image, the VAE and PyTorch buffers. That leaves 6 GB, which is enough for a browser and a text editor, but not for a second model.
On 32 GB the Q8 version is the upper limit. At full precision (bf16) the model alone would take about 24 GB, and without splitting the work into stages the system would have to use swap. I have no comparable timing from the project on 29 October, so I do not compare these numbers.
How to run Kontext in ComfyUI on a Mac
I install the whole setup in a separate Python environment, so library versions do not mix with other projects. This order worked for me:
Kontext on a Mac step by step
- 01ComfyUI and PyTorch with MPSI install ComfyUI in a separate venv and check that PyTorch sees the Mac's graphics chip (the mps device).
- 02GGUF nodesThe ComfyUI-GGUF add-on lets you load the model and the T5 encoder in their Q8 versions.
- 03Model files and diskI keep the largest Wan model (Q6) on the internal disk, because once, when it was read from a USB disk, the server stopped working. In this measurement Kontext read its files from the external SSD over USB without errors, and loading them is included in the times given.
- 04Instruction separatelyI encode the text once, save the result and start the server again so the encoder frees its memory.
- 05Edit and previewA few random seeds, one comparison sheet, and picking the best variant by eye.
It is also worth running ComfyUI with SDPA attention from the PyTorch library (the --use-pytorch-cross-attention flag). Without this flag ComfyUI on a Mac uses another, slower method (sub-quadratic). In the project I measured SDPA attention as about three times faster on the Mac’s graphics chip for the same work. It is one flag when the server starts, and it shortens every edit and every video segment in later stages.
An instruction instead of a mask
The classic way to edit a photo with such a model is inpainting: you mark the area to change with a mask and describe what should appear there. Kontext works differently. Black Forest Labs’ paper on Kontext describes how the input photo goes into the model together with the instruction, so the same model can both create and edit images, without a mask. The model decides on its own which pixels to change, based on the instruction. That saves a lot of time: I do not have to trace the hand with the microphone or the lamp, one sentence is enough.
It has a downside too. The model may change something I did not mention, for example move a shadow slightly or change the tone of a wall. That is why I always compare the result with the original on the slider and look at the face zoomed in. In the project I also checked face similarity with numbers, using a separate model, but for a single frame a careful look is faster and more reliable.
What to watch out for when editing frames
The first thing is the image proportions. ComfyUI’s FluxKontextImageScale node resizes the photo to the nearest resolution Kontext works with and crops the centre of the frame. In my case that is 752 × 1392 pixels, a ratio of 0.540 instead of the 0.5625 of vertical 9:16 video. In the project this made the start frame come out stretched by 4%, which I only caught in the check before the full run. The result has to be pasted back into the frame exactly where that crop came from. In the comparison above I crop the original the same way, so the slider shows the same pixels.
The second thing is choosing the random seed. Each seed gives a slightly different lamp and fills the place of the hand differently. In the project I made three variants, looked at them side by side and picked seed 2. A script could pick the variant whose face is most similar to the original, but here I prefer to choose myself, because the whole film depends on this one frame.
The third thing is the licence. According to the FLUX.1 dev non-commercial licence:
- you may use the outputs for any purpose, including commercial ones, except training models that compete with FLUX,
- the model itself may only be run for non-commercial purposes,
- outputs must carry an AI content label where the law requires it,
- every output must pass a content filter or a human review before it is shared.
That is why I treat my test as a non-commercial measurement of the model. If you want to use Kontext in paid work or in a service for clients, choose a Black Forest Labs commercial licence (a paid add-on for Kontext) or the [pro] version through the API. The Q8 file comes from the GGUF conversion made by QuantStack and has the same licence as the original.
Local or API
Black Forest Labs also offers Kontext through an API, as a paid cloud service. According to BFL’s pricing, FLUX.1 Kontext [pro] costs USD 0.04 per image and [max] USD 0.08. Three variants of one frame are therefore 12 to 24 cents. On my own Mac I do not pay per image, but I pay with time: the three edits took 17.4 minutes of graphics chip work in total.
With one frame per reel the API is more convenient: three variants in Kontext [pro] cost about 12 cents, and the Mac is not busy for 17 minutes. The version on your own computer makes sense in three situations:
- the material is private and you do not want to send it to someone else’s servers,
- you need dozens of attempts with different instructions that can run overnight,
- you want full control of the graph in ComfyUI, for example to put Kontext between other steps.
I write more about image and video tools in my guide to image, video and voice with AI, and about labelling such content in my article on C2PA and labelling AI content.
Verdict
Kontext did exactly what I needed: it changed objects and the background, and the face stayed recognisable. On a 32 GB Mac mini it runs stably on one condition: the text encoder and the image model work one after another, not at the same time. For single fixes I would pick the API, and for work on private material and many attempts the version on your own computer.
In the previous part I measured the language model Qwen3.6 on a Mac mini. This test is non-commercial, in line with the model’s licence, and new parts of the series appear every day.